Free · PDF
The KV Cache — from zero
26 pages · about a 25-minute read
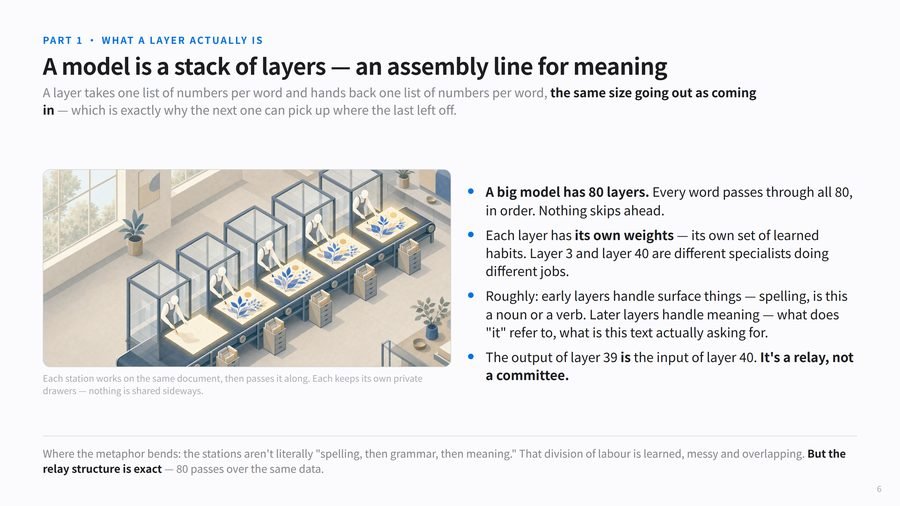
- What a layer actually is, and why a model stacks 80 of them.
- What Q, K and V mean — as a meeting where everyone wears a name tag.
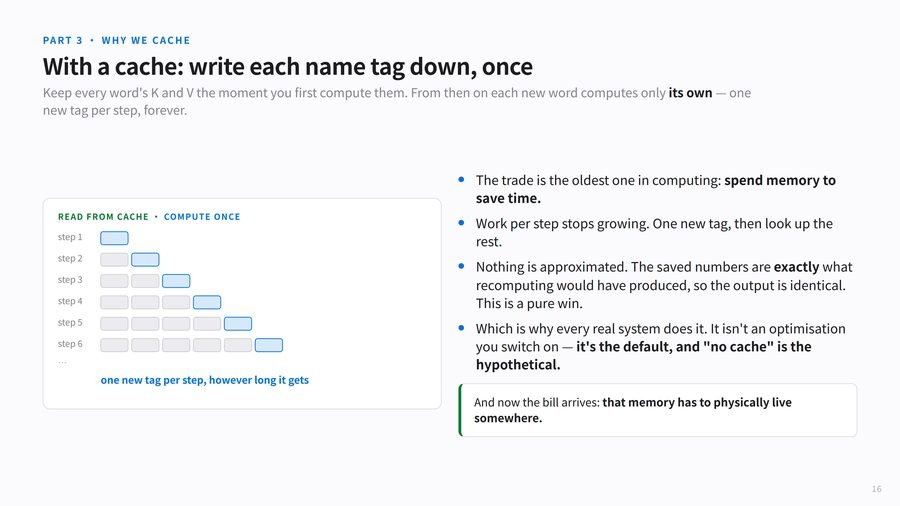
- Why two of them are kept and one is thrown away. That lopsided fact is the whole cache.
- The actual arithmetic: 320 KB per word, 40 GB per conversation, and where every number comes from.
- Why a busy server holds more conversation than model — and what that does to the price of every word.
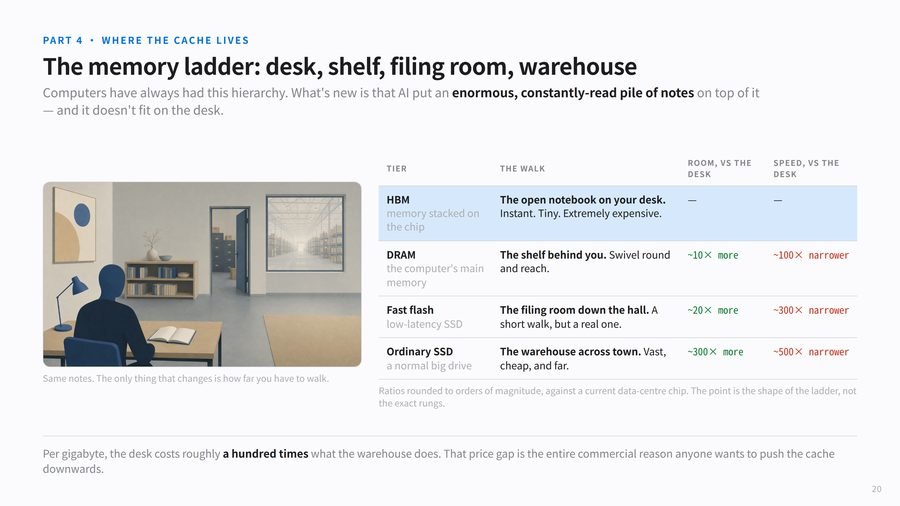
- Why storage companies suddenly care, and what they shipped about it.
Create a free account & download
Free account, no card. Already have one? Sign in and the file appears here.
Download the PDF (26 pages)
It's yours — the link doesn't expire. Found a mistake? Say so in the community; every number in it is checkable.
Written by Nathan Wang (AI-Nate) — ai-nate.com
Want to build the things this describes?
The guide explains how the machinery works. The cohort is where you build on top of it — live, hands-on, with the systems running by the end.
See the cohort